Hybrid gateway for Claude Code
A local LiteLLM proxy that runs Claude Code with a strong planner and cheap executors, and tracks what every session costs.
Set it up
git clone git@github.com:mSulleza/litellm-hybrid-gateway.git ~/litellm
cd ~/litellm
python3 -m venv venv && ./venv/bin/pip install 'litellm[proxy]'
cp litellm.env.example litellm.env      # add the provider keys
cp agents/*.md ~/.claude/agents/        # the delegation subagents
lms load qwen/qwen3-coder-30b --context-length 65536 --gpu max
./run.sh                                # the proxy, on 127.0.0.1:4000
The context length on the Qwen load matters. LM Studio’s default of 8,192 tokens is too small for Claude Code’s requests, the call errors, and the proxy quietly falls back to DeepSeek. Everything still works and you save nothing.
Use it
alias local-code="$HOME/litellm/claude-hybrid.sh"
local-code
local-code starts Claude Code against the proxy. The main loop runs on GLM-5.2. When it delegates, deepseek-coder takes coding jobs with a clear spec and qwen-grunt takes mechanical work like renames, formatting and running tests, for free on the local model. /model opus puts a frontier model back on the loop for a session that needs judgement. Plain claude is untouched and stays on the subscription.
See what it cost
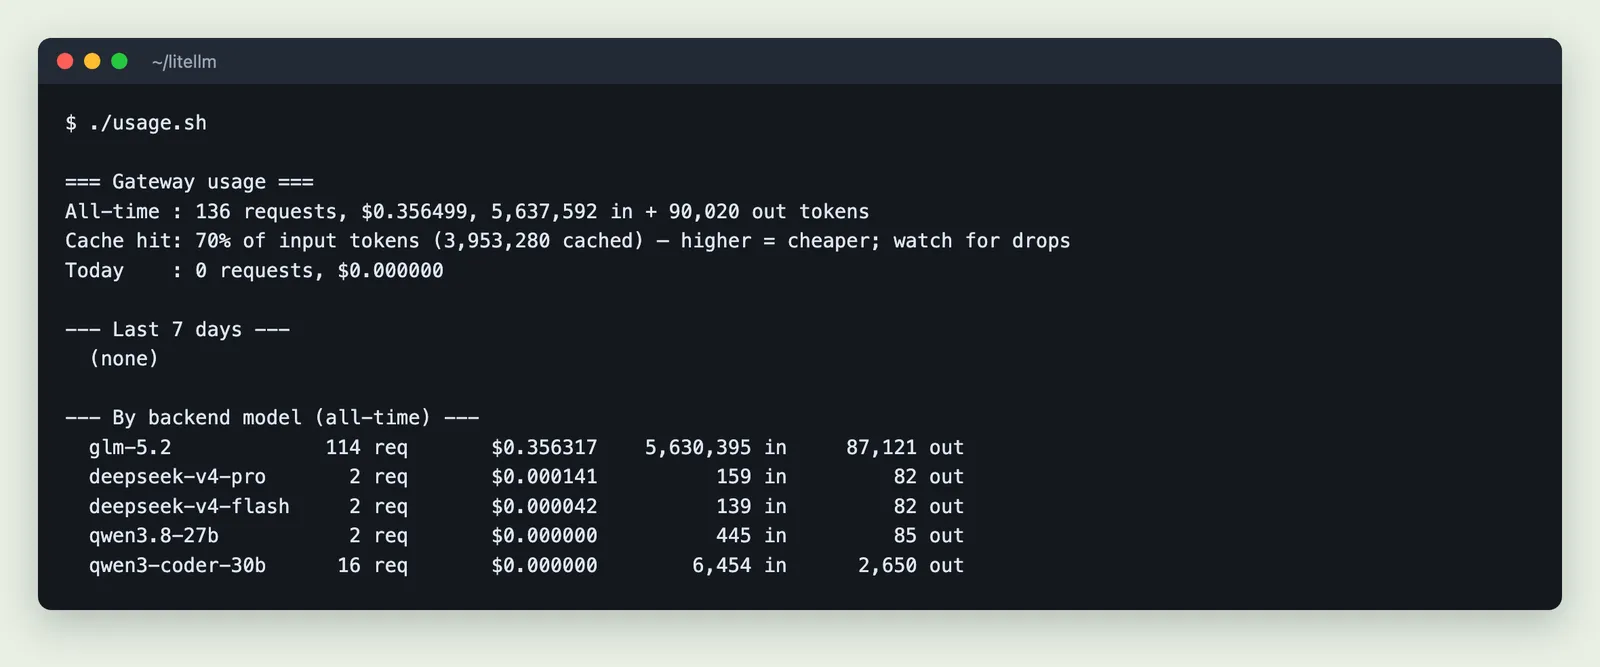
usage.sh in a terminal. Every request is logged with its model, tokens and cost.
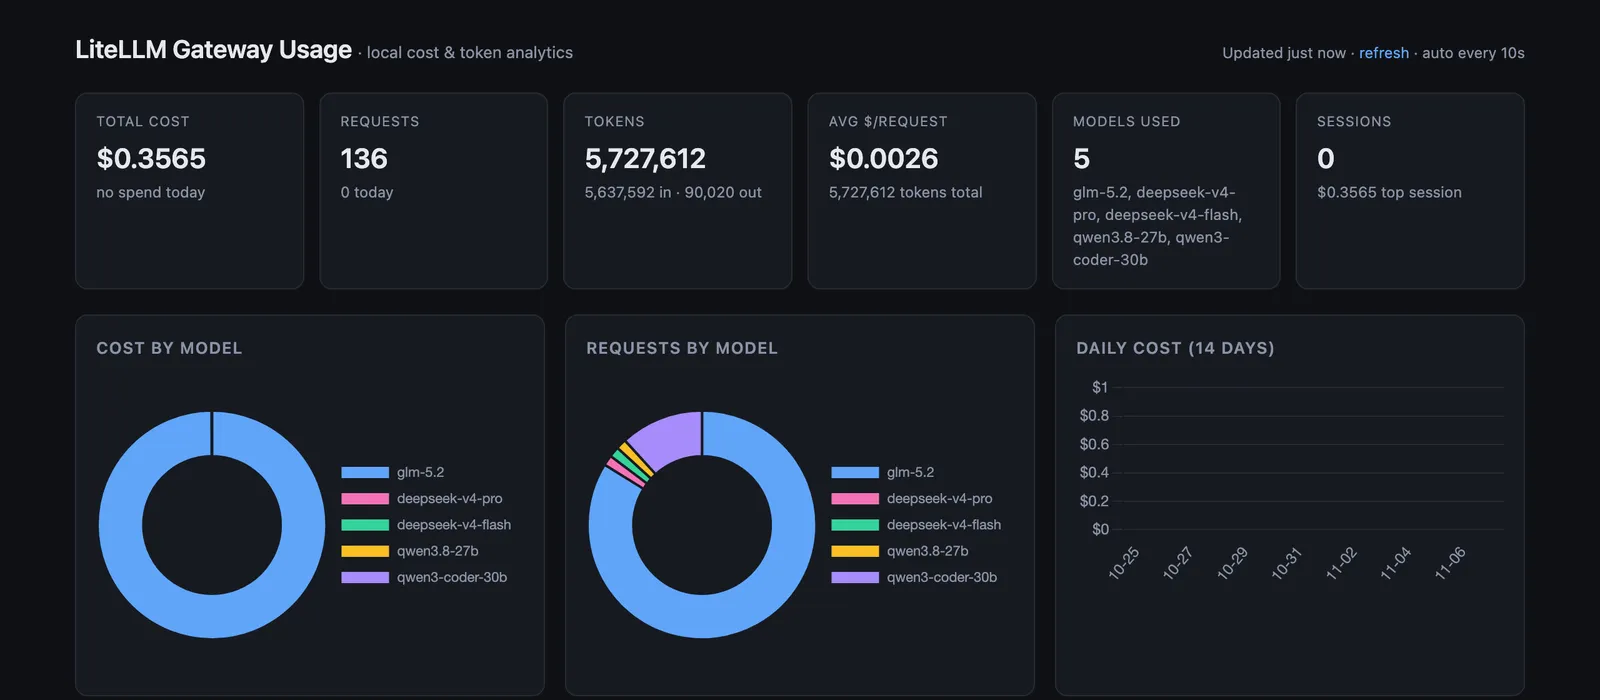
Claude Code stamps each request with its session id, and a LiteLLM callback writes it to a local SQLite file with the cost. local-usage opens the dashboard at the top of this page, on 127.0.0.1:4040, with cost by model, by day and by session.
More on the local tier: Running a 27B coding model on my laptop.